Retrieval-augmented generation (RAG) adds a retrieval layer between a user’s question and an AI model. Instead of asking a model to rely only on its training data, a WordPress application retrieves relevant content from a controlled knowledge base and includes that content in the model request.
For WooCommerce agencies, this makes it possible to build assistants that answer questions about products, shipping policies, return rules, subscriptions, compatibility, and internal operating procedures without fine-tuning a model for every client.
The core RAG architecture
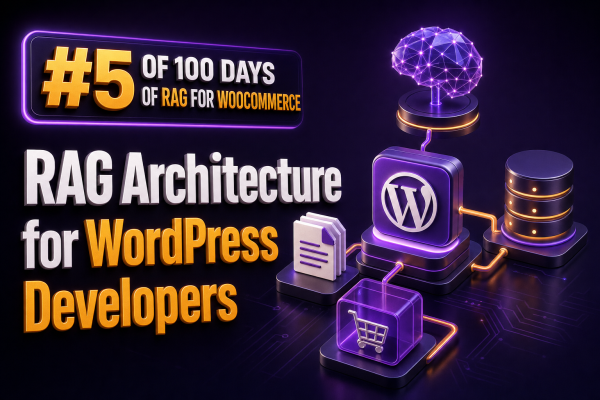
A production RAG system normally contains two separate pipelines:
- Ingestion: WordPress content is collected, cleaned, chunked, embedded, and stored in a searchable index.
- Query: A user question is embedded or otherwise analyzed, relevant chunks are retrieved, and those chunks are supplied to the language model as context.
The language model should not be responsible for finding the source material. Its role is to interpret the retrieved context and produce a response that follows the application’s instructions.
Ingestion pipeline
- Detect new or updated WordPress and WooCommerce content.
- Convert the content into plain text while preserving useful metadata.
- Split the text into retrieval-sized chunks.
- Generate an embedding for each chunk.
- Store the embedding, text, source URL, post ID, product ID, language, and permissions metadata in a vector-capable data store.
Query pipeline
- Accept a question from a customer, store manager, or support agent.
- Apply access-control and tenant filters before retrieval.
- Retrieve candidate chunks using semantic search, keyword search, or a hybrid of both.
- Optionally rerank the candidates using a cross-encoder or a second model.
- Build a bounded prompt containing the selected context.
- Generate the answer and provide citations or source links where appropriate.
Where WordPress fits
WordPress is usually the system of record and the user interface, not the vector database. A custom plugin can coordinate the workflow, while embeddings and retrieval are handled by an external service or a database extension such as PostgreSQL with pgvector.
A practical plugin architecture might contain these components:
- Content adapter: Reads posts, pages, product data, attributes, taxonomies, documentation, and selected order or policy data.
- Normalizer: Removes navigation, shortcodes, tracking markup, and irrelevant presentation content.
- Indexer: Creates or updates chunks after content changes.
- Retriever: Sends a query and metadata filters to the search service.
- Prompt builder: Combines instructions, retrieved context, and the user’s question.
- Response handler: Returns the answer, citations, logging data, and error information to the frontend or REST API client.
Indexing WordPress and WooCommerce content
Do not index every rendered page as one large document. A product page may contain a short description, long description, specifications, variation information, shipping notes, and customer-facing policy text. These sections have different retrieval value and should usually be represented as separate, labeled chunks.
Useful metadata for a WooCommerce chunk includes:
post_idandproduct_idpost_type, such asproduct,page, orshop_order- Product SKU, category, brand, and attributes
- Language and site or tenant identifier
- Publication status and visibility rules
- Source URL and the last modified timestamp
- A content section such as
specifications,returns, orshipping
Use hooks to mark content as stale rather than performing a remote embedding request during a normal admin save request. For example, a plugin can enqueue an indexing job after a product changes and process it through Action Scheduler.
<?php
add_action( 'save_post_product', function ( $post_id, $post, $update ) {
    if ( wp_is_post_revision( $post_id ) || 'publish' !== $post->post_status ) {
        return;
    }

    as_enqueue_async_action(
        'my_rag_index_product',
        array( 'product_id' => $post_id ),
        'my-rag'
    );
}, 10, 3 );
The worker should retrieve the current product data, delete or replace the previous chunks for that product, generate new embeddings, and record the indexing result. This avoids stale answers after a price, stock policy, or specification changes.
Chunking strategy
Chunking should follow the structure of the information rather than an arbitrary character limit. Headings, product attributes, FAQ entries, and policy clauses are often better boundaries than fixed slices of HTML.
Keep enough surrounding context for a chunk to make sense on its own. A chunk containing “It is covered for two years” is weak if it does not identify the product or warranty being discussed. Prefix chunks with useful labels, for example:
Product: Alpine Waterproof Jacket
Section: Warranty
Content: The manufacturer warranty covers material defects for two years...
Chunk sizes depend on the embedding model and the content type. Smaller chunks improve precision but can omit context. Larger chunks provide context but can reduce retrieval accuracy and consume more prompt tokens. Measure retrieval quality using representative WooCommerce questions instead of selecting a size by convention.
Retrieval and filtering
Semantic similarity alone is not sufficient for a store. A question about a product in the French storefront should not retrieve an unpublished English product or another client’s catalog. Apply metadata filters before or during vector search.
Common filters include:
- Site or tenant ID for agency-managed multi-store platforms
- Language and country
- Published status and catalog visibility
- Product category, brand, or product ID
- User role or support-agent permissions
- Document type, such as public policy versus internal operations documentation
Hybrid retrieval is often effective for WooCommerce because product SKUs, model numbers, and exact policy terms are important. Combine semantic search with keyword or full-text search, then merge and rerank the results. A query for SKU ALP-2048 should not depend entirely on an embedding model recognizing the identifier.
Building a WordPress REST endpoint
A custom REST endpoint can accept a question and return an answer with citations. Authentication and authorization must be enforced server-side. Do not expose a provider API key or allow the browser to select arbitrary retrieval filters.
<?php
register_rest_route( 'my-rag/v1', '/answer', array(
    'methods'             => WP_REST_Server::CREATABLE,
    'callback'            => 'my_rag_answer',
    'permission_callback' => function () {
        return is_user_logged_in();
    },
    'args'                => array(
        'question' => array(
            'required'          => true,
            'sanitize_callback' => 'sanitize_textarea_field',
        ),
    ),
) );
The callback should validate the question length, derive permitted scopes from the current user, call the retrieval service, construct the model request, and return structured data such as answer, sources, and request_id. Add rate limiting and request logging before exposing the endpoint to a public storefront.
Prompt construction and grounding
Retrieved text is evidence, not an instruction. The prompt should clearly separate system rules, the user question, and source context. Tell the model to use only the supplied context for factual store-specific claims and to say when the context does not contain an answer.
System rules:
- Answer using the supplied store context.
- Do not invent prices, stock levels, delivery dates, or policy exceptions.
- If the context is insufficient, say that the information is unavailable.
- Cite the relevant source when one is provided.

Store context:
[Source 1] Product: Alpine Waterproof Jacket ...
[Source 2] Returns policy ...

Customer question:
Can I return this jacket after wearing it once?
Limit the number of retrieved chunks and the total context size. More context is not automatically better; irrelevant chunks can cause the model to combine policies or confuse similar products.
WooCommerce-specific security concerns
Order data, customer details, wholesale pricing, and internal support notes should not be placed in a public retrieval index. Treat every indexed document as data with an access policy.
- Keep customer-specific order retrieval separate from public product retrieval.
- Filter by the authenticated customer’s user ID before retrieving order data.
- Remove email addresses, phone numbers, addresses, and payment details unless they are strictly required.
- Never send payment card data or sensitive credentials to an embedding or generation provider.
- Use separate indexes or namespaces for each client and environment.
- Log which sources were retrieved so incorrect answers can be investigated.
Operational design for agencies
Remote embedding and generation calls can fail, time out, or become expensive. Index asynchronously, retry transient failures with limits, and store an indexing status for each source. A deployment should make it possible to reindex one product, one content type, one site, or the entire knowledge base.
Track at least the following metrics:
- Indexing success and failure rates
- Time since a published document was last indexed
- Retrieval latency and number of results
- Generation latency and token usage
- Answers with no supporting source
- Human feedback and escalation rate
For client projects, maintain a test set of real questions covering products, variations, returns, shipping, subscriptions, and unsupported requests. Evaluate whether the correct source appears in the top results before evaluating the wording of the generated answer. A fluent answer based on the wrong product is still a retrieval failure.
Recommended implementation boundary
Keep WordPress responsible for content ownership, permissions, editorial workflows, and the customer-facing experience. Keep the retrieval service responsible for embeddings, vector search, reranking, and index operations. Communicate through authenticated server-to-server requests and pass explicit tenant, language, and permission metadata on every query.
This boundary lets an agency replace a vector provider or language model without rewriting WooCommerce templates, while preserving WordPress as the authoritative source for the information customers and staff are allowed to use.