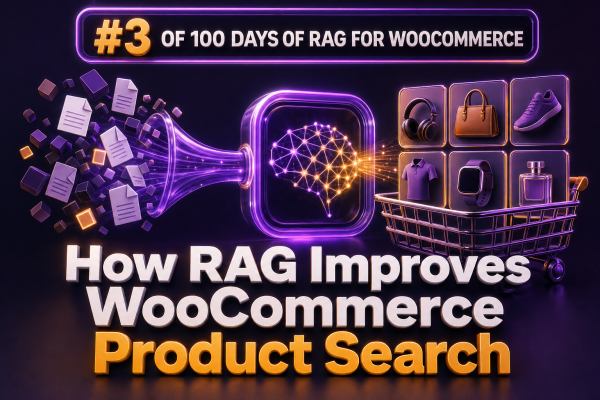
WooCommerce product search often fails for reasons that have little to do with the catalog itself. Customers search with use cases, attributes, compatibility requirements, and informal language, while product data is usually organized around titles, SKUs, taxonomies, and custom fields. Retrieval-augmented generation (RAG) improves this experience by combining product retrieval with a language model that can interpret the shopper’s request and present grounded results.
What RAG Adds to WooCommerce Search
A conventional WooCommerce search generally matches query terms against product titles, descriptions, SKUs, categories, tags, and selected metadata. This works well for exact terms such as a SKU or brand name, but it is weaker for queries such as “a waterproof jacket for cold cycling commutes” or “replacement filter for the compact espresso machine.”
A RAG-based search flow separates the task into two stages:
- Retrieve: Find relevant products or product chunks using keyword search, semantic vector search, structured filters, or a hybrid of these methods.
- Generate: Give the retrieved product data to a language model so it can explain matches, compare options, answer follow-up questions, or refine the search.
The model should not invent products, prices, stock status, specifications, or compatibility information. Those details must come from the retrieved WooCommerce data or from authoritative connected systems.
A Practical WooCommerce RAG Architecture
A production implementation commonly includes the following components:
- Catalog extraction: Read products, variations, attributes, categories, tags, prices, stock status, images, and relevant custom fields through the WooCommerce REST API, scheduled exports, or direct application integrations.
- Normalization: Convert inconsistent product data into a stable representation. For example, map “navy,” “dark blue,” and an internal color attribute to a consistent searchable value where appropriate.
- Document and chunk creation: Build searchable records for each product and, when necessary, separate records for specifications, compatibility, sizing, care instructions, or variation-level details.
- Indexing: Store text fields in a keyword search engine and embeddings in a vector database or search platform that supports vector queries.
- Query processing: Classify the shopper’s intent, extract structured constraints, create an embedding, and run keyword, vector, or hybrid retrieval.
- Response generation: Pass only the selected product facts and relevant instructions to the language model.
Product Data Preparation
Embedding a raw product description is rarely enough. Agencies should create a deliberate searchable representation that preserves business-critical fields. A product record might contain content such as:
Product: Alpine Shell Jacket<br>Brand: North Ridge<br>Category: Men's waterproof jackets<br>Use cases: cycling commute, hiking, wet-weather travel<br>Features: 20,000 mm waterproof rating, taped seams, helmet-compatible hood<br>Sizes: S, M, L, XL<br>Color: Navy<br>Compatibility: Fits over standard cycling layers<br>Availability: In stockKeep authoritative values such as price, inventory, sale status, and variation availability in structured fields as well as in the text representation. Structured fields can be filtered or validated without relying on semantic similarity.
Use Hybrid Retrieval Instead of Vector Search Alone
Semantic search is useful when the shopper uses different words from the catalog. Keyword search remains essential for exact identifiers, brand names, model numbers, technical standards, and uncommon terms. A hybrid strategy combines both signals.
For example, a query for “AB-204 replacement cartridge” should strongly favor an exact SKU or compatibility match. A query for “quiet filter for a small office” benefits more from semantic matching across product descriptions and specifications.
A typical retrieval pipeline can:
- Extract filters such as category, size, color, price range, brand, and stock requirement.
- Run a lexical query against product titles, SKUs, attributes, and descriptions.
- Run a vector query against product or specification embeddings.
- Merge and deduplicate the candidate results.
- Apply hard filters for requirements such as stock, region, product visibility, or compatibility.
- Rerank the remaining candidates using relevance, business rules, and query-specific signals.
Hard constraints should be enforced outside the language model. If a customer asks for an in-stock product under a specific price, the application should filter using current commerce data rather than asking the model to decide whether a product qualifies.
Handling Variations and Custom Product Fields
WooCommerce variations introduce important indexing decisions. A parent product may have shared content, while each variation has its own SKU, price, stock quantity, dimensions, or attributes. Indexing only the parent product can produce answers that name an available product but not an available size or color.
Consider indexing a parent record plus variation records. Each variation can include inherited product information and its own searchable fields:
- Variation ID and SKU
- Parent product ID
- Size, color, material, or other variation attributes
- Current price and sale price
- Stock status and purchasability
- Variation-specific dimensions or compatibility data
At query time, retrieve the parent product for customer-friendly presentation but validate the selected variation against live WooCommerce data before displaying a purchase option.
Grounded Product Answers
The generation prompt should define what the model may and may not do. It should instruct the model to use only supplied catalog facts, identify missing information, avoid unsupported claims, and distinguish between a product match and a recommendation.
A useful response format can include the product name, why it matches, relevant specifications, current price, availability, and a product URL. If the retrieved records do not establish compatibility, the answer should say that compatibility is unconfirmed and request the missing model number or product detail.
For example, a grounded answer to “Which replacement filter fits my Model X brewer?” should rely on a compatibility field or an approved compatibility table. Similar wording, product similarity, or a high vector score is not proof of compatibility.
Keeping Retrieval Data Current
WooCommerce catalogs change frequently. Prices, inventory, visibility, product descriptions, and variation attributes must be synchronized with the retrieval index.
Use event-driven updates where possible. Product creation, update, deletion, stock changes, and taxonomy changes can trigger targeted reindexing. A scheduled reconciliation job should still compare WooCommerce with the search index and repair missed events.
For fast-changing fields, store the value in a transactional or commerce data service and retrieve it at request time. This is especially important for inventory, pricing, promotions, and regional availability. Embeddings do not need to be regenerated for every stock change if those fields are handled separately.
Example Request Flow
For a query such as “Show me a black waterproof backpack under $150 that fits a 16-inch laptop”, an application can process the request as follows:
- Extract the category, color, waterproof requirement, maximum price, and laptop-size requirement.
- Apply structured filters for category, color, price, and indexed laptop compatibility.
- Use keyword and vector retrieval to find products described with related terms such as “water-resistant,” “rain cover,” or “commuter pack.”
- Rerank candidates using the strength of the waterproof and laptop-fit evidence.
- Fetch current price and stock data from WooCommerce or a trusted commerce cache.
- Generate a concise answer using only the verified candidate records.
This approach is more reliable than sending the complete catalog to a language model and asking it to select a product. Retrieval reduces context size, improves latency, and makes the evidence available for auditing.
Agency Implementation Considerations
Before building a custom RAG service, agencies should define which search problems require semantic interpretation and which are better solved with native WooCommerce filters or an established search platform. RAG is valuable for natural-language discovery, product comparison, specification questions, and conversational refinement. It should complement, not replace, deterministic catalog operations.
Track retrieval and answer quality separately. Useful metrics include zero-result rate, click-through rate, add-to-cart rate, conversion rate, filter extraction accuracy, top-result relevance, citation or evidence coverage, and unsupported-claim rate. Create an evaluation set from real customer queries, including misspellings, synonyms, SKU searches, compatibility questions, and ambiguous requests.
Access controls and catalog visibility also need to be enforced during retrieval. Draft, private, hidden, region-restricted, or customer-specific products must not enter the model context unless the current user is authorized to see them. Log query interpretation, retrieved product IDs, applied filters, and final product data so relevance issues can be diagnosed without storing unnecessary personal information.
When RAG Is the Right Fit
RAG is a strong fit when a WooCommerce catalog contains rich descriptions, technical specifications, compatibility information, or multiple ways to express the same customer need. It is less suitable as the sole mechanism for exact SKU lookup, real-time pricing, inventory decisions, checkout logic, or other operations that require deterministic results.
The most dependable implementation combines semantic retrieval for intent, keyword search for precision, structured filters for constraints, live commerce data for volatile fields, and a language model for explanation. This division of responsibilities improves product discovery while keeping the final search experience tied to the actual WooCommerce catalog.