RAG guides for WordPress & WooCommerce

Great end-to-end RAG tutorial from and with ZenML

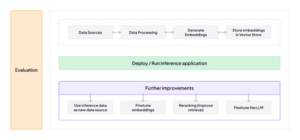
The tutorial (all code, which is refreshing). 1️⃣ RAG 2️⃣ Evaluation and metrics 3️⃣ Reranking 4️⃣ Finetuning embeddings 5️⃣ Finetuning LLMs The image shows a deployment on Google Vertex (Apache Airflow) pipelines.   ZenML is an open-source framework designed to simplify the creation of Machine Learning (ML) pipelines. It helps engineers and data scientists manage the lifecycle of ML models, from experimentation to deployment, in a structured and reproducible way. Key Features of ZenML Pipeline-Oriented Design: ZenML encourages you to break your ML workflows into modular, reusable, and composable steps, such as data preprocessing, training, evaluation, and deployment. Flexibility with Integrations: ZenML integrates with various tools and frameworks, such as TensorFlow, PyTorch, Scikit-learn, and others. It supports deployment solutions like Kubernetes, AWS SageMaker, and others. Integration
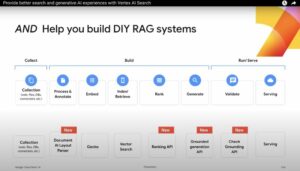
Provide better search and generative AI experiences with Vertex AI Search

Vertex AI search is (finally) catching up with advanced RAG features like VLM document parsing, chunking, citations, re-ranking, grounding generation/verification.  As usual, you will have to choose between an all-in-one closed-source monolytic solution like this or aggregating the best open-source solutions. But this now looks, at least on paper, like a solid RAG/search solution with the key advantage of being serverless and scalable end-to-end. Similar to the new features of Amazon Bedrock knowledge bases https://aws.amazon.com/bedrock/knowledge-bases/. It is not easy to clone this with disparate components without investing time and money. Contact us if you want to build a RAG in your WordPress.  

Fine-tuning a reranker with synthetic LLM generated data and LLM+human annotations

Great post from HumanSignal labelstud.io to fine-tune a Cohere reranker with synthetic LLM generated data and LLM+human annotations: Generate synthetic queries from documents with a LLM (OpenAI gpt4-o here) Extract results from your retrieval system for all synthetic queries Create a label project for reranking tasks with triplet-loss (positive, hard-negative) Upload query/results in the label studio Pre-label query/results with a LLM reranker’s back-end (OpenAI gpt4-o here) Let humans complete the pre-labeling Send labeled query/results to a LLM reranking fine-tuner (Cohere here) Test your new fine-tuned reranked retrieva Original post: https://labelstud.io/blog/improving-rag-document-search-quality-with-cohere-re-ranking/  

What is RAG and how does it work

Nowadays, text generation is making a big wave thanks to LLMs (Large Language Models). Trained on large amounts of publicly (or sometimes privately) accessible data, these models can complete various language related tasks such as conversation (chatbot), question answering and even advising. They impact many sectors like writing, coding and marketing. But what about search? Well you’re at the right place because that is what RAG (Retrieval Augmented Generation) is about.   What does RAG do ?   RAG, as it’s name implies, combines both search and AI-based text generation. It has become a very trendy topic recently since it is capable of delivering the same capabilities as LLMs while remaining a more reliable source of information. This is because, when integrated into a RAG